AI: Intelligent search and query routing using Tool Calling
In previous experiments with AI in the serdg.net project, mechanisms for generating embeddings, semantic search and RAG (Retrieval-Augmented Generation) were implemented. Thanks to this, the application gained the ability not only to find articles by semantic similarity, but also to form answers to user questions based on published materials.
The next stage of development was to combine the existing capabilities into a single interface using AI Tool Calling — a mechanism that allows the language model to choose appropriate application tools depending on the content of the user's request. The main task was to provide the user with the ability to search for articles, ask questions about their content, and combine these operations without the need to manually select the processing method.
Identifying the problem and defining the task
As the serdg.net project evolved, the set of functions for working with articles gradually expanded. Initially the application provided access to published materials, then mechanisms for generating embeddings, semantic search and obtaining answers using RAG appeared. As a result, several independent ways of interacting with the site's content were formed, each solving its own task.
However, searching for articles and generating answers based on their content are fundamentally different operations, although a user may formulate corresponding requests in the same way — in natural language. For example, the query "Find articles about .NET in German for 2026" implies a regular search with filtering and pagination, whereas the question "How was Azure Container Apps used in projects?" requires analysis of published materials and the formation of an answer using RAG. A more complex scenario is also possible: "Find articles about OpenAI and compare the approaches described in them." In that case it is necessary first to identify suitable materials and then analyze their content.
One possible solution was to create separate interfaces for search, contextual questions and combined operations. However, such an approach would require the user to understand the application's internal mechanisms and to independently choose the appropriate tool. Instead, it was decided to expand the existing Any question field, turning it into a universal interaction point with the site's functionality.
The main task was to implement a mechanism capable of interpreting the user's request and automatically determining the necessary sequence of actions. At the same time, it was required to preserve the existing RAG, add search and filtering of articles via natural queries, support combined operations and reuse existing services without duplicating business logic. Additional requirements were to minimize the number of calls to the LLM, control related costs and preserve the familiar presentation of results in Angular.
A particularly interesting technical challenge was the decision-making mechanism. The language model should determine the appropriate tool and form the parameters for its call without receiving direct access to the database or the application's internal infrastructure. Thus, the task was not to hand over business logic to AI, but to create an intelligent routing layer between the user interface and the already implemented services. The chosen mechanism for solving this task was AI Tool Calling.
Theoretical elaboration: AI Tool Calling
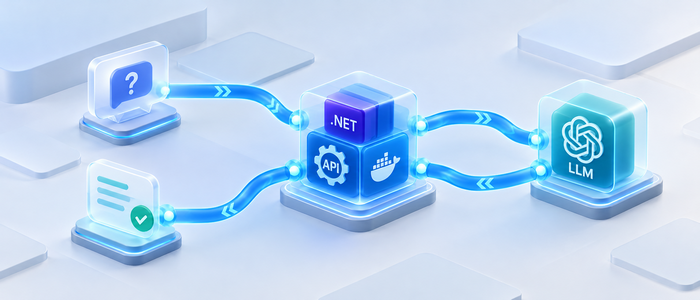
To combine different mechanisms for processing user requests, the approach AI Tool Calling (also known as Function Calling) was chosen. Its main idea is that the language model not only generates text but can also determine which application operations need to be performed to solve the task. At the same time, the model itself does not get direct access to business logic or infrastructure: it selects the appropriate tool and forms the parameters for its call, while execution remains under the application's control.
In a typical interaction with an LLM the user sends a text request based on which the model generates a response. In simplified form this process looks like the following:
Tool Calling extends this scheme by providing the model with descriptions of available tools. Each tool has a specific purpose, a set of parameters and rules of use. Receiving the user's request, the LLM maps it to the tool descriptions and can form a structured call with the necessary arguments. The application validates the received data, performs the corresponding operation and processes its result. Depending on the scenario, the result may be returned directly to the user or passed back to the model for forming the final response.
The fundamental difference is the separation of decision-making and operation execution. The LLM determines the user's intent and suggests the appropriate call, while the application itself decides whether such an operation is permissible, validates the arguments and calls the corresponding service. Thus, the language model is used as an intelligent routing mechanism rather than as a replacement for existing business logic.
The advantage of this approach is especially noticeable when handling natural language requests. For example, the phrase "Show German articles about Docker published this year" can be parsed using keywords and predefined rules. However, such an implementation quickly becomes complex because the same intentions can be expressed in very different formulations, including in multiple languages. Using an LLM allows interpreting the meaning of the request and converting it into a structured set of parameters:
language = "de"
  text = "Docker"
  dateFrom = "2026-01-01"
  dateTo = "2026-12-31"
After receiving these parameters, further processing is performed by the application's usual services. Thus, the model is responsible for interpreting the user's intent, while search, filtering, sorting and pagination remain deterministic operations. For correct handling of relative time expressions such as "this year", "last month" or "the last 12 months", the router is additionally given the current date. This allows the model to take the temporal context of the request into account, although the correctness of the formed boundaries still requires validation.
Another capability of Tool Calling is sequential use of multiple tools. For example, answering a combined request may require first finding suitable articles, then identifying relevant fragments of their content and only after that forming an answer using RAG. Such operations can be executed via several consecutive tool calls or combined into a predefined scenario on the application side. The second option is especially convenient when the execution order is known in advance and does not require independent planning by the language model.
That is why for this task using a full-fledged AI agent was not necessary. The number of available operations is limited, their purpose is predefined, and possible sequences of execution are fairly simple. Controlled Tool Calling with a fixed set of tools allows gaining the main advantages of intelligent routing without the additional complexity characteristic of autonomous agent systems.
At the same time, Tool Calling does not guarantee absolute correctness in request processing. The language model may misinterpret the user's intent, choose an inappropriate tool or form incorrect arguments. Additional complications include token costs, latencies when calling the LLM and the need to protect against attempts to influence internal application logic via user text.
Therefore, a reliable implementation implies the use of a strictly defined list of available tools, mandatory argument validation, limits on the number of calls and control of the overall token budget. Critically important rules must be enforced by program code rather than only by instructions to the language model. This approach allows using the flexibility of LLM for interpreting requests while preserving predictability and controllability of actual operations execution.
Thus, AI Tool Calling is a mechanism for interaction between a language model and traditional software services. Its main value is not in handing application control to artificial intelligence, but in the ability to transform freely formulated user requests into concrete, controlled operations. This principle was the basis for implementing intelligent routing in serdg.net.
Implementation of article search and filtering
The first practical step was preparing a search mechanism that could be used both directly by the application and via AI Tool Calling. Instead of creating a separate implementation for the language model, the existing business logic was used, augmented with a specialized layer for processing search requests. This approach avoided duplication of functionality and ensured consistent search rules regardless of how it is invoked.
Criteria are passed using a structured request model containing parameters for text search, language, time range, sorting and pagination. All conditions can be combined within a single request, and their processing does not depend on the data source — the user interface or the language model.
| Parameter | Purpose |
|---|---|
text |
Text search |
language |
Article language: en, de or ru |
dateFrom |
Start date |
dateTo |
End date |
sort |
Sorting: newest or oldest |
page |
Page number |
pageSize |
Page size |
The obtained parameters are validated, normalized and transformed into conditions understood by the existing search mechanism. A simplified example of preparing these conditions in C# looks as follows:
var searchParameters = new
  {
    SearchQuery = request.Text,
    LanguageCode = request.Language,
    CreatedFrom = ParseDate(request.DateFrom),
    CreatedBefore = ParseDate(request.DateTo)?.AddDays(1),
    OrderBy = request.Sort == "oldest"
      ? "CreationDate asc,Id asc"
      : "CreationDate desc,Id desc",
    IsPublished = true,
    IsHidden = false,
    Page = request.Page!.Value,
    PageSize = request.PageSize!.Value
  };
Search conditions are applied together: a query can simultaneously restrict the article language, contain a search phrase and set a time interval. Text matching is performed on the title, short description and HTML content of the corresponding localization. In this case a regular text search is used, while semantic search remains the task of a separate mechanism based on embeddings.
Date filtering has certain specifics. Since the existing model does not have a separate publication date field, the search uses CreationDate — the article creation date. To include the final day, the upper bound of the time interval is converted to the start of the next day. For example, when searching for materials up to December 31 inclusive, the query receives an exclusive upper bound of January 1 of the next year.
Because search parameters can be formed by the LLM, a number of restrictions are provided. Only certain fields and sort values are allowed, and conditions IsPublished = true and IsHidden = false ensure selection of only published and visible articles. The default page size is 20 records, the maximum allowed value is 50. For stable pagination, sorting by date is supplemented with sorting by Id, which makes it possible to unambiguously order articles with the same creation date.
As a result, a universal search mechanism was formed, equally available to traditional application components and AI Tool Calling tools. At the same time all data processing remains in the existing program layer, and the language model is responsible only for converting the user's request into structured parameters. This allows expanding search capabilities without significant changes to the AI-integration architecture.
AI Routing implementation
After preparing the search mechanism, the next step was implementing intelligent routing of user requests. The main task was to determine the necessary operation based on natural language and pass its execution to the appropriate application component.
For this purpose three tools were defined: SearchArticles for searching and filtering articles, AskArticles for getting contextual answers via RAG and SearchAndAskArticles for combined requests that imply first searching for materials and then analyzing their content. This set covers the main interaction scenarios with the application without creating excessive complexity when choosing an operation.
Routing is implemented on the server side using IChatClient from Microsoft.Extensions.AI. Available tools are registered via AIFunctionFactory.CreateDeclaration, and their parameters are described using JSON Schema. This allows passing to the language model not only operation names but also the structure of permissible arguments, required data types and the purpose of each tool.
When processing a request the model receives system instructions, the user's message and descriptions of available tools. Based on this information it determines the appropriate operation and forms structured arguments for its execution. A simplified example of configuring an LLM call looks like this:
var response = await client.GetResponseAsync(
    state.Messages,
    new ChatOptions
    {
      Tools = Tools,
      AllowMultipleToolCalls = false,
      MaxOutputTokens = limits.MaxOutputTokens,
      ResponseFormat = ChatResponseFormat.Json
    },
    ct);
An important feature is that tool selection and its actual execution are separated. The model forms a request to call a specific operation, after which the application validates the received parameters and executes the necessary actions itself. The result can be returned directly to the user or used for further processing.
This mechanism can be conveniently illustrated by the request: "Find articles about Azure Container Apps in Russian and explain how deployments are organized in them." In this case the user expects both a list of suitable materials and an explanation based on their content. Therefore, the most appropriate operation is SearchAndAskArticles. In a simplified representation the model's choice and the formed arguments might look like the following:
{
    "tool": "SearchAndAskArticles",
    "arguments": {
    "text": "Azure Container Apps",
    "language": "ru",
    "sort": "newest"
    }
  }
After receiving and validating the arguments, the application performs a search for articles according to the specified conditions. Then the identifiers of the found materials are passed to the RAG mechanism, limiting the area of subsequent semantic search. Thus, first a selection of articles matching the user's request is formed, and only after that semantic search within them is performed. This ensures consistency of results: the generated answer is based on materials that satisfy the initial search criteria.
Since different tools imply different ways of presenting information, the server returns a structured result with its type indicated in the resultType field. For a regular search SearchResult is used, containing a list of articles and pagination data. A contextual question returns AnswerResult with the answer text and links to sources. A combined operation forms a CombinedResult that merges both structures.
A simplified example of the combined response structure:
{
    "resultType": "CombinedResult",
    "status": "answered",
    "answer": "...",
    "sources": [],
    "articles": {
    "items": [],
    "totalItems": 0,
    "page": 1,
    "pageSize": 20,
    "totalPages": 0
    },
    "search": {
    "text": "Azure Container Apps",
    "language": "ru",
    "sort": "newest",
    "page": 1,
    "pageSize": 20
    },
    "coverageLimited": true
  }
The structure above demonstrates the principle of combining search and generated answer results; the contents of answer, sources and articles depend on the actually found materials. Normalized search parameters are additionally returned, which can be reused by the client, for example when switching pages. The coverageLimited field allows indicating that the generated answer is based on a limited selection of materials.
For integration with Angular the existing Any question field was connected to a new server endpoint supporting all three scenarios. The received resultType determines how the information is displayed: search results are shown as article cards, contextual answers as text with links to sources, and the combined result contains both elements simultaneously.
At the same time the search results are not converted by the language model into plain text. Existing Angular components are reused for their display, preserving the familiar appearance of cards and navigation mechanisms. Text generation is used only where content analysis is actually required.
As a result, AI Routing combined several independent application capabilities into a single user interface. The language model determines the user's intent and selects the appropriate tool, while search execution, context extraction and result formation remain the responsibility of specialized mechanisms. This allows leveraging the advantages of natural language without changing the fundamental operation principles of the existing application.
Architectural decisions and interesting implementation details
When implementing the new functionality, the main task was to maximally use the existing application architecture while preserving separation of responsibilities between components. As a result ArticleRequestRouter is responsible for request interpretation and tool selection, ArticleQueryService performs article search and filtering, and ArticleAnswerService provides RAG functionality. Such separation allows evolving each component independently, simplifies testing and makes it possible to add new tools without significant changes to the existing business logic.
One of the most important decisions was to limit the RAG search scope when processing combined requests. For this purpose the RagSearchScope object is used, containing the language and the identifiers of the articles among which information needs to be searched:
public sealed record RagSearchScope(string Language,IReadOnlyList<int> TopicIds);After performing a regular search the identifiers of articles on the current results page are passed into this object. Then RAG searches for relevant fragments exclusively among the selected materials. Filtering is performed before vector similarity sorting and selecting the top-K fragments. Thus, found information pertains to articles that match the original search criteria. Special handling for an empty selection is provided: if suitable articles are absent, RAG does not automatically switch to the entire knowledge base.
Since tool selection is performed by the language model, its actions must be controlled. ArticleRequestRouter validates the names of called tools and passed arguments, rejecting unknown operations and incorrect parameters. Interaction is limited to four rounds of calls to the routing model, one tool call per round and a maximum of three tool calls. Input and output tokens, the overall token budget, execution time and request frequency are additionally controlled. These limitations ensure predictable application behavior, reduce the risk of incorrect tool usage and allow control over AI-related costs.
For the same reason pagination handling was optimized. After the initial request the system already has the structured search parameters obtained with the help of the LLM. Therefore when moving to the next page there is no need to call the model again and reinterpret the same query. Along with the results the client receives normalized filters that are used in subsequent requests with a changed page number. ArticleRequestRouter recognizes such a scenario and directly calls ArticleQueryService, bypassing the LLM. This reduces latency and token consumption. If the initial request was combined, the generated answer is also retained when switching pages and is not recomputed.
However, this approach has an important limitation. The combined answer is formed based on articles on the current search results page, and RAG additionally selects from them the most relevant fragments given the available token budget. Therefore the obtained answer cannot be considered an exhaustive analysis of all found materials. To explicitly indicate this limitation, a coverageLimited flag was added to the result model. If it is set to true, Angular displays a corresponding notification. This is an important aspect of designing AI interfaces: the user should understand not only the result of request processing but also the boundaries of the information on which this result is based.
Another feature was support for multiple languages. Since serdg.net contains articles in Russian, English and German, it is necessary to distinguish between the response language and the language of materials being searched. By default they coincide, however the user may, for example, ask a question in Russian and request German articles. In that case search and context extraction by RAG are performed for German materials, and the final answer is generated in Russian. This preserves a unified interface while taking into account the multilingual structure of the application.
Special attention was paid to testing. Working with LLMs creates certain difficulties: model responses are not always deterministic, and numerous calls to a real AI provider increase test execution time and costs. Therefore, automated tests use controlled responses of IChatClient, allowing simulation of tool selection and verification of the application's reaction to specific tool calls. Integration tests use real application services with a test SQLite database, while calls to the AI are mocked. This approach allows verifying routing, filtering, security constraints and error handling without depending on the behavior of the real model. On the Angular side additional checks verify correct display of different result types and preservation of the combined answer when switching pages.
As a result it was possible to maintain a fairly simple and controllable architecture: AI is responsible for interpreting the user's intent, existing services perform necessary operations, and the application manages their sequence, constraints and presentation of results. Adding intelligent routing practically does not affect the already implemented search and RAG mechanisms.
Conclusion
Working on this functionality allowed practically exploring another way of applying large language models in traditional software systems. Unlike previous experiments with text generation, Embeddings and RAG, the main interest here was the use of LLM for interpreting user intents and decision-making.
One important conclusion was understanding that introducing AI does not necessarily require significant changes to the existing architecture or the use of complex agent systems. Sometimes a small specialized component that solves a specific problem — difficult to implement by traditional means — is sufficient.
At the same time, such solutions require a somewhat different approach to development and testing. In addition to correctness of program code, it is necessary to consider the quality of request interpretation, possible variability of model behavior and the dependence of the result on the formulation of the user's request.
This experiment was a useful continuation of familiarization with AI technologies and their practical application in .NET. In the future it would be desirable to pay more attention to quantitative evaluation of LLM performance, comparison of different models and searching for scenarios where applying AI truly provides advantages over traditional algorithms.